


AI assistants are everywhere, but how useful are they really? A new evaluation platform called LifeVal aims to find out by testing how well AI models handle the practical, everyday tasks we all face, setting a new standard for real-world utility.
A New Yardstick for AI Helpfulness
On November
2, 2026, OpenAI introduced LifeVal, a benchmark designed to measure how effective AI systems are at helping people with their daily chores. Instead of testing an AI's ability to pass academic exams or solve complex coding problems, LifeVal focuses on real-world utility. The goal is to see if an AI can be a truly helpful personal assistant, capable of guiding a user through multi-step tasks like finding childcare, managing a household budget, or navigating government paperwork. OpenAI revealed it has been using LifeVal internally for the past year to track and improve its models, aiming to create agents that can take meaningful action, not just provide answers.
Moving Past Abstract Puzzles
For years, AI progress has been measured by performance on specialized tasks like chess, Go, or answering knowledge-based questions. While impressive, these benchmarks don't always reflect how useful an AI is in day-to-day life. LifeVal represents a significant shift by evaluating 'agentic' capabilities—the AI's ability to complete a job, not just talk about it. To build this new test, OpenAI started by analyzing how people actually spend their time, using large-scale studies like the American Time Use Survey and the Multinational Time Use Study. They then conducted a new survey with nearly 4,000 people to identify which tasks people most wanted help with from a personal assistant.
What Does 'Everyday' Mean?
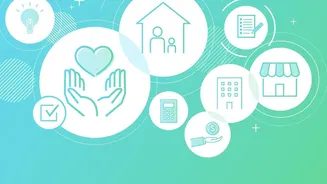
The tasks included in LifeVal span seven core categories: caregiving, health, education, household administration, personal finances, shopping, and accessing government services. The challenges are designed to be practical and multi-faceted. Examples include complex scenarios like finding a kindergarten for a child after a move, planning meals for a parent with a new diabetes diagnosis, or organizing a group of community volunteers to prepare for a flood. This approach tests an AI's ability to research, compare options, handle digital forms, and integrate with external tools to achieve a concrete outcome, rather than simply providing a summary of information.
Early Performance Insights
Alongside the announcement, OpenAI released some of its internal scores. The results show a clear progression, with the company's GPT-5.2 model scoring 49.3%, while the more recent GPT-5.6 achieved 80.0%. The latest model, GPT-6 Astra, scored 80.6%, suggesting that gains in this area are becoming harder to achieve. However, it's important to note that these are self reported scores. OpenAI has not yet released the full dataset, scoring method, or opened the benchmark for third party models to be tested. This means that while the numbers show progress within OpenAI's own systems, they can't yet be used to compare different AI assistants across the market.
Why Practical Benchmarks Matter
The introduction of LifeVal signals a crucial change in how the tech industry might soon measure AI progress. By focusing on practical, everyday utility, it pushes developers to build models that are genuinely helpful, not just knowledgeable. This shift could lead to AI assistants that are more reliable and capable of handling the 'life admin' that consumes so much of our time. For consumers, it could eventually provide a clearer picture of which AI assistant is truly the best at getting things done. While a polished summary from an AI is nice, a tool that can reliably check school deadlines, fill out the forms, and confirm submission is far more valuable. LifeVal is a step toward measuring and encouraging that deeper level of assistance.