
Artificial intelligence can write poetry and pass medical exams, but can it help you plan a family budget or find the right childcare? OpenAI's new benchmark, LifeVal, suggests the next frontier for AI is less about abstract genius and more about practical,
everyday helpfulness.
What is LifeVal?
On November 2, 2026, OpenAI introduced LifeVal, an internal evaluation framework designed to measure how well its AI models perform on the messy, multi-step chores of daily life. Instead of just testing an AI's ability to answer a question correctly, LifeVal assesses whether it can successfully guide a user through a complete task from start to finish. This marks a significant pivot in how AI progress is measured. The goal is to move beyond scoring well on standardized tests and toward creating a truly useful personal assistant that can manage real-world responsibilities.
The Old Yardstick: Academic Benchmarks
For years, the AI industry has relied on academic benchmarks to prove how 'smart' models are becoming. Tests like MMLU (Massive Multitask Language Understanding) evaluate models across dozens of subjects like history, law, and maths, using a multiple-choice format. While useful for tracking raw knowledge and reasoning, these benchmarks have limitations. A high score doesn't necessarily translate into practical ability. An AI might know the theory behind budgeting but fail to help you actually create a household budget that works with your specific income and expenses. This gap between academic performance and real-world utility is what LifeVal aims to bridge.
How LifeVal Measures Helpfulness
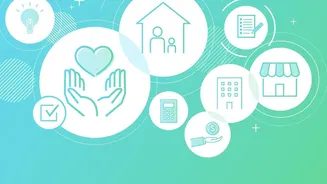
To build LifeVal, OpenAI analyzed data from large-scale time-use studies to understand how people spend their days. They also surveyed nearly 4,000 people to find out which tasks they would most want an AI assistant to handle. The result is a benchmark built around 169 tasks in seven key areas: caregiving, health, education, household administration, personal finances, shopping, and accessing government services. Scenarios include complex, real-world problems like finding a new kindergarten after a move, creating a meal plan for a relative with a new health diagnosis, or organizing volunteers to prepare for a flood. The evaluation focuses on whether the AI can complete the task, not just provide information about it.
Why This Shift Matters
By changing the evaluation metric, OpenAI is changing the development target. When the goal is to ace an academic test, engineers will optimize for that. But when the goal is to successfully book a car inspection or navigate government paperwork, the entire development process shifts toward practicality and reliability. This move signals a maturation of the AI industry, from proving what's possible to delivering what's valuable. For users, it promises a future where AI assistants are less like trivia champions and more like capable partners that can genuinely lighten the mental load of managing modern life.
The Road Ahead
Despite the promise, LifeVal is still an internal tool, and OpenAI has not released the full dataset or detailed scoring rubric for outside scrutiny. This makes it difficult for independent researchers to verify the results or compare different AI models. Furthermore, evaluating 'helpfulness' is inherently more subjective than grading a multiple choice test. Defining what a 'successful' outcome looks like for a complex personal task is a major challenge. As OpenAI has used LifeVal internally for the past year to drive improvements, the reported scores for its models have risen significantly. However, the company notes that strong performance on the benchmark doesn't guarantee flawless real world results every time.