


The Old Way: A Shared Town Square
First, let's talk about Symmetric Multiprocessing, or SMP. For a long time, this was the go-to design for computers with more than one processor. In an SMP system, all processors are created equal. They share a single, central pool of memory and are managed
by one operating system. Think of it like a group of chefs all working in one kitchen. They share the same pantry, the same refrigerator, and the same countertop space. This setup is simple and effective—any chef can grab any ingredient with the same amount of effort. In computing terms, this means any processor can access any part of the memory at the same speed. For everyday multitasking and many business applications, this model works beautifully and provides a straightforward way to boost performance by adding more processors.
The Bottleneck Problem
The SMP kitchen works great with a few chefs, but what happens when you have dozens? They start bumping into each other, waiting in line for the pantry, and generally getting in each other's way. This is the fundamental limitation of SMP. As you add more and more processors, they all have to compete for access to that single, shared memory bus. This competition creates a bottleneck, and after a certain point—often around 8 or 16 processors—adding more CPUs yields diminishing returns. The highway to the memory gets congested, and performance stalls, no matter how many powerful processors you have. This scalability problem is what drove the industry to find a new way forward.
The New Way: Private Desks and Hallways
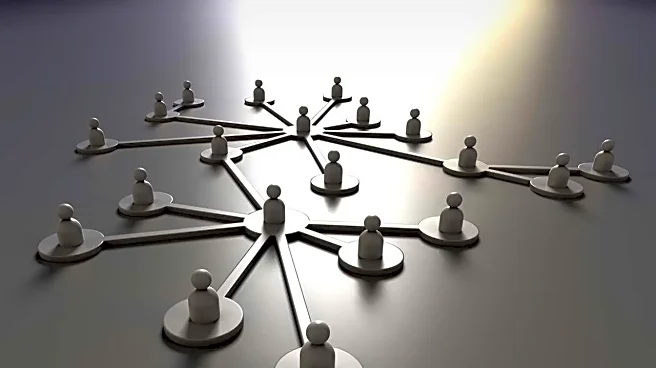
Enter Non-Uniform Memory Access, or NUMA. This is the architecture that powers virtually all modern multi-socket servers. NUMA solves the bottleneck problem by fundamentally changing the layout. Instead of one giant shared kitchen, imagine each processor (or group of processors) gets its own smaller, local kitchen. In NUMA, the system is divided into 'nodes,' with each node containing its own processors and its own dedicated memory. A processor can access its own 'local' memory extremely quickly. However, it can still access the memory of another node—called 'remote' memory—but it takes longer because the request has to travel across a special high-speed interconnect. This is where the 'Non-Uniform' name comes from: memory access time is not the same everywhere; it depends on location.
Real-World Impact in a Production System
In a production environment, the difference between SMP and NUMA isn't just theoretical—it directly impacts application performance. For software that isn't 'NUMA-aware,' performance can be unpredictable and surprisingly poor. An application thread might be running on a processor in one node while constantly needing data stored in the memory of another node. This constant fetching of remote memory adds latency and can cause performance to fluctuate wildly. Databases are especially sensitive to this. Maximum performance is achieved when a database's processing threads and the data they need are kept on the same NUMA node. The same principle applies to virtualization. Hypervisors need to be NUMA-aware to ensure a virtual machine's virtual CPUs and its assigned memory stay within the same physical node to avoid performance penalties. Modern AI and machine learning workloads, which are incredibly memory-intensive, also see significant performance gains when they are optimized for NUMA, keeping data as close to the processing cores as possible.