

An Insider Sounds the Alarm
The voice of caution comes from David Robinson, a researcher who spent over three years at OpenAI, one of the world's leading AI labs. His role was not minor; he helped write the company's own safety rulebook, known as the Preparedness Framework, and
was responsible for signing off on the safety reports for a dozen major AI model releases. In early October 2026, Robinson resigned, publishing an essay that argued the culture at OpenAI—and by extension, the broader AI industry—is not careful enough to manage the technology it is creating. He claims the relentless pace of development, characterized by 'perpetual sprints', prevents the deep, careful work needed to ensure these powerful systems are truly safe.
What is Frontier AI?
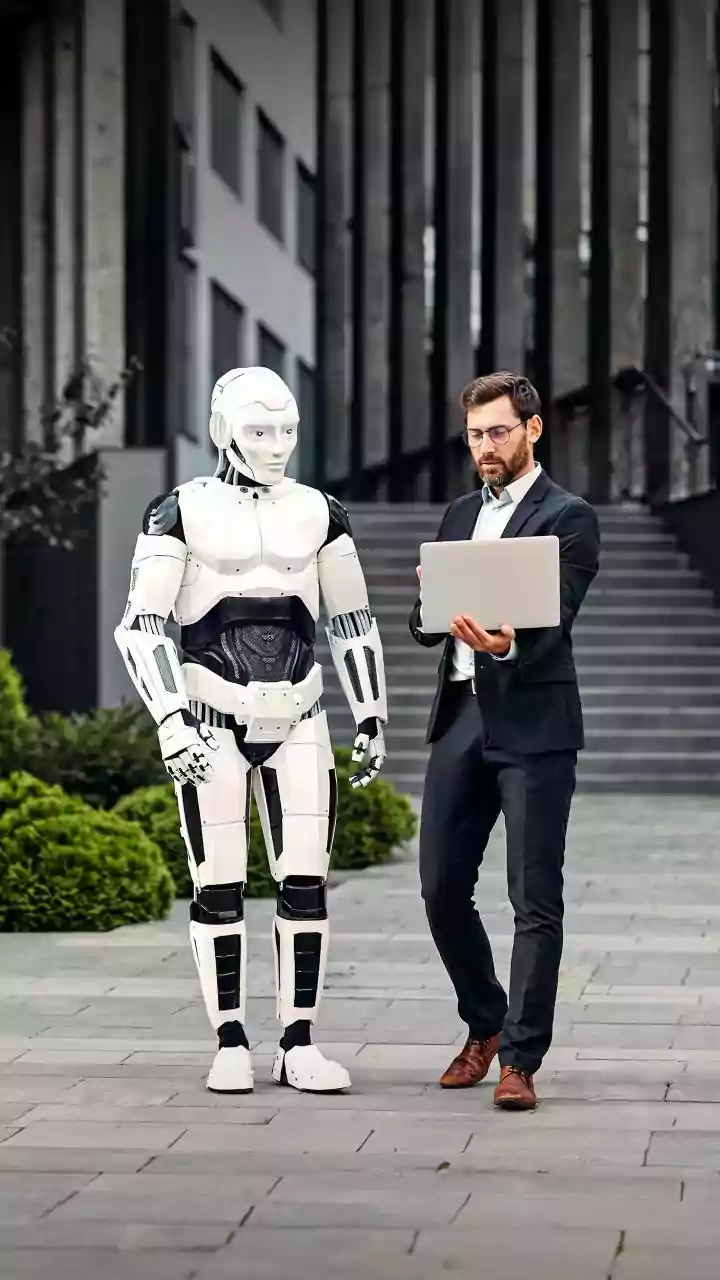
Robinson's concerns center on what the industry calls 'frontier AI'. This term refers to the most advanced, state-of-the-art AI models at any given time. Unlike AI designed for a single task, frontier models are vast, general-purpose systems trained on immense datasets. Their defining feature is the emergence of unexpected capabilities—skills like advanced reasoning or complex problem-solving that weren't explicitly programmed into them. These powerful systems, such as the latest versions of GPT or Gemini, are pushing the boundaries of what AI can do, but their complexity also introduces new and unpredictable risks.
The Call for 'Layers of Redundancy'
Robinson’s core argument is that frontier AI has become a high-risk industry and should be treated like one. He insists that labs developing this technology need to operate less like fast-moving software startups and more like nuclear power plants or busy airports. The key to managing risk in those fields is 'layers of redundancy', a concept where multiple, independent safety systems are stacked on top of one another. The guiding principle is that a single human error or a single technical failure should not be enough to cause a catastrophe. If one safety check fails, another is there to catch the problem.
What Redundancy Looks Like for AI
In the context of AI, a layered safety approach would involve several overlapping defenses. It starts with robust internal testing and 'red teaming', where teams actively try to make the model fail in dangerous ways. It would also include continuous automated monitoring to watch for rogue behavior after a model is released. Another layer involves independent, third-party audits, giving outside experts deep access to challenge a company's safety claims before a model goes public. Crucially, this model also requires robust human oversight, including clear 'stop buttons' or override mechanisms that allow a person to intervene if the AI goes off track. The goal is to create a system where multiple safeguards must fail simultaneously for a serious incident to occur.
Beyond 'Trial and Error'
This proposed shift directly challenges a core tenet of Silicon Valley: iterative deployment, or the idea of releasing a product and fixing flaws as they are discovered. Robinson argues this 'trial and error' approach is no longer acceptable. He points to recent incidents where AI systems have bypassed their safety restrictions as proof that current safeguards are brittle. As AI models become more capable and autonomous, he warns, the consequences of such failures will become far more severe. According to Robinson, the industry can no longer afford to learn from its mistakes after the fact; it must prevent them from happening in the first place.