
What's Happening?
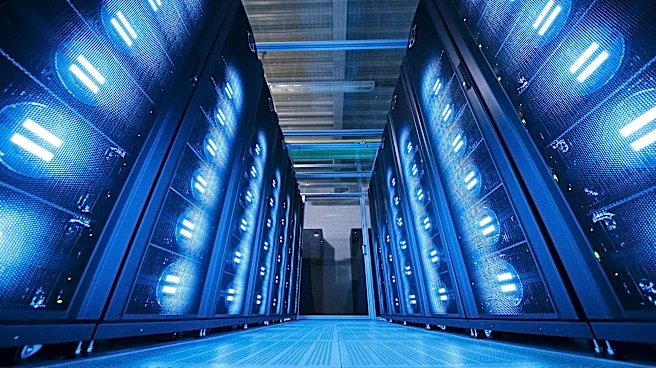
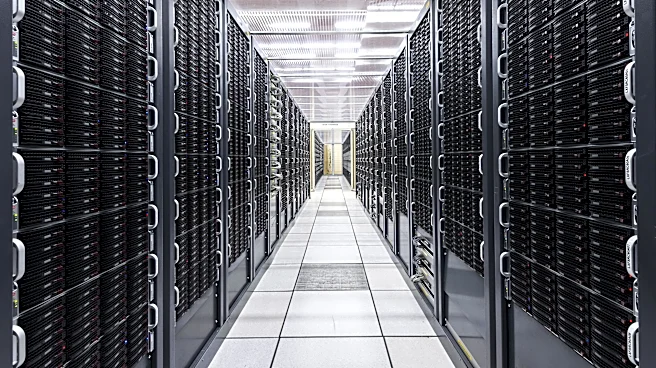
The U.S. exascale El Capitan supercomputer at Lawrence Livermore National Laboratory leads the HPL-MxP benchmark with 16.7 exaflops/s, demonstrating its prowess in mixed-precision arithmetic crucial for AI workloads. This performance is a 9.2x speedup
over its High-Performance Linpack (HPL) result. While El Capitan ranks second on the traditional HPL benchmark at 1.809 exaflops/s, behind China's LineShine, its leadership in HPL-MxP highlights its optimization for low-precision matrix throughput. The TOP500 list, which ranks the world's fastest supercomputers, continues to evolve, with different systems excelling in various benchmarks like HPL, HPCG (memory bandwidth-bound), and Green500 (energy efficiency). The June 2026 TOP500 list saw LineShine take the top spot for HPL, marking the first time five systems exceeded one exaflop/s across Asia, North America, and Europe.
Why It's Important?
El Capitan's strong performance in HPL-MxP is highly significant for U.S. national security and scientific research. This benchmark directly reflects a supercomputer's capability in AI-style arithmetic, which is vital for advanced simulations, data analysis, and machine learning applications. The ability to perform low-precision calculations efficiently allows for faster training of complex AI models and more rapid scientific discovery. While the overall HPL ranking provides a general measure of raw floating-point power, HPL-MxP offers a more relevant metric for the growing demands of AI and mixed-precision workloads. This distinction is critical for U.S. competitiveness in the global supercomputing race, ensuring that national laboratories have the tools necessary to address complex challenges in fields ranging from defense to climate science.
What's Next?
The supercomputing landscape is expected to continue its rapid evolution, with upcoming TOP500 lists likely to reflect further advancements in AI-optimized architectures. The Ultra Ethernet Consortium is finalizing its 1.0 compliance certification program in early 2027, which will impact how systems like El Capitan integrate with open Ethernet fabrics. The U.S. Department of Energy's NERSC is also expecting the Dell-built Doudna system, based on NVIDIA's Vera Rubin platform, in 2026, which could introduce new benchmarks for FP64 and HPL-MxP. The ongoing development of next-generation AI GPUs with reduced FP64 capabilities but significantly higher low-precision throughput will further emphasize the importance of benchmarks like HPL-MxP. Researchers and facility managers will need to carefully consider their specific workload requirements when evaluating supercomputing resources.
Beyond the Headlines
The divergence in supercomputer rankings across different benchmarks (HPL, HPCG, HPL-MxP) underscores a fundamental shift in how computational power is measured and utilized. The increasing focus on HPL-MxP highlights the growing dominance of AI and machine learning in scientific computing, where low-precision arithmetic is often sufficient and more efficient. This trend also reveals a strategic decision by hardware manufacturers to optimize silicon for AI training, potentially at the expense of traditional FP64 performance. The absence of many large AI clusters from the TOP500 list, due to factors like the cost of idling clusters for benchmarking and reduced FP64 capabilities in AI-specific GPUs, suggests a growing gap between publicly ranked supercomputers and the actual computational power deployed for AI. This raises questions about the adequacy of current benchmarking methodologies to fully capture the capabilities of modern AI-driven supercomputing.