
What's Happening?
On November 15, 2026, Lawrence Livermore National Laboratory (LLNL) and its partners announced the operational results of ElMerFold on the El Capitan supercomputer. This technical paper, titled 'Exascale Distillation Workflows for Protein Structure Prediction
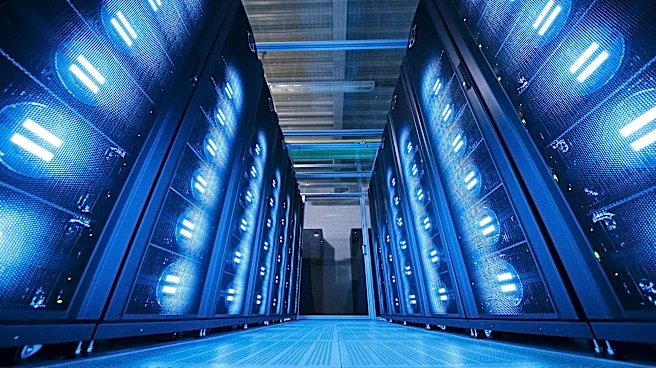
on El Capitan,' has been selected as an ACM Gordon Bell Prize finalist. The team, led by principal investigator Brian C. Van Essen and technical lead Nikoli Dryden of LLNL, along with Mohammed AlQuraishi of Columbia University and Nicholas Malaya of AMD, is scheduled to present their findings on November 17, 2026, at SC26 in Salt Lake City. ElMerFold successfully generated high-accuracy 3D structural predictions for over 41 million monomer proteins in approximately 11 hours, providing a foundational synthetic training dataset for the development of OpenFold3, an open-source alternative to proprietary biomolecular foundation models. The workflow scaled across up to 11,200 nodes and 44,800 AMD Instinct MI300A Accelerated Processing Units (APUs) on El Capitan, achieving a sustained throughput of 2,400 structures per second and a peak of 6,718 structures per second. This represents a significant speedup, compressing six to eight days of supercomputer time into roughly 11 hours.
Why It's Important?
This achievement is crucial for the field of structural biology and artificial intelligence, particularly in democratizing access to advanced protein structure prediction. Modern biomolecular foundation models, such as AlphaFold and OpenFold, rely heavily on 'self-distillation,' which involves generating millions of high-confidence synthetic structures from uncharacterized sequence databases. Historically, this process has been a significant bottleneck, requiring substantially more computational power than training the final neural network. ElMerFold directly addresses this barrier by creating a 41-million-structure synthetic library, essential for training OpenFold3 openly. This open-source approach allows academic laboratories to explore pathogen structures, study neglected diseases, and engineer enzymes without the restrictions of proprietary cloud services. The successful implementation on El Capitan, which utilizes AMD's unified APU architecture, demonstrates the potential for innovative hardware and leading-edge science to push the boundaries of AI, impacting drug discovery, material science, and biosecurity.
What's Next?
Following its presentation at SC26, El Capitan will transition to classified national security workloads for the NNSA’s Advanced Simulation and Computing (ASC) stockpile stewardship program. Consequently, open-science biological workflows, including those developed for ElMerFold, will be transferred to Tuolumne, El Capitan’s unclassified companion system, which operates at roughly one-tenth the scale but uses the same MI300A APU architecture. The LLNL, Columbia, and AMD team plans to use Tuolumne to finalize the training of OpenFold3, aiming for fully open model weights and code releases for the scientific community. Additionally, the team intends to extend the ElMerFold framework to model multimers and multi-protein complexes, with the goal of simulating up to one billion biomolecular interactions. The Gordon Bell Prize finalist presentation on November 17, 2026, will be a key event where the ACM committee evaluates this research alongside other exascale achievements.
Beyond the Headlines
The development of ElMerFold and the subsequent open-sourcing of its foundational data for OpenFold3 highlight a broader shift towards open science in high-performance computing and AI. This move has significant implications for research access, safety evaluations, and benchmark reproducibility, particularly as frontier biological foundation models intersect with federal biosecurity directives and export controls under America's AI Action Plan. University research compliance officers and institutional biosafety committees will need to evaluate data governance and access controls for these macromolecular prediction libraries. Furthermore, the curation of petabyte-scale synthetic libraries demands adherence to FAIR data principles (Findable, Accessible, Interoperable, and Reusable), ensuring that public outputs are systematically managed and differentiated from empirical crystallographic coordinates. This emphasis on open access and verifiable results could accelerate scientific discovery and foster greater collaboration within the global research community.